For years people have said we don't really know why AI hallucinates. To me the reason is pretty obvious, and has been for a while. It's simple, and it has big implications for how you use AI and how far you can trust it.
The same root cause explains why models can be tricked into doing things they shouldn't. Once you see it, the way to build reliable and secure AI systems gets clear. Stop trusting the model to police itself.
How LLMs Generate Text
Start with how large language models generate content. Not how they're built. That's a whole other discussion. How they generate.
They generate one little chunk of text at a time. At each step the model builds a list of the most likely next chunks and picks one with some randomness. The most likely options get picked most often. Less likely options get picked less often. But they do get picked.
That holds even for models that do thinking and review their work. Thinking is still generated one chunk of text at a time, from a randomness distribution.
The key detail is that each chunk depends on the chunks that came before it. Every pick shapes the next pick. That one detail explains almost everything that follows.
Why AI Hallucinates
A hallucination, or really any clearly wrong answer, starts when the model picks a chunk that's a little off the rails. The next chunk builds on that one, so it's a little more off the rails. Then a little more. Then a little more.
Each step in a bad direction makes the next step in a bad direction more likely. Thinking models reduce this. They can sometimes catch themselves and readjust. Sometimes, not always.
Why AI Hallucinations Aren't Fully Solvable
This is part of why I say LLMs have fundamental flaws that aren't 100% solvable. Changing this would take a completely different architecture, one that doesn't generate one chunk of text at a time.
The practical implication is simple. AI output will pretty much always need to be checked, and it will always need to be evaluated. You always want to trust but verify.
Can AI Models Be Trusted?
Hallucination is one example of a bigger category. The model goes off track a certain percentage of the time. Security failures come from the same place.
I did a bunch of red teaming research across a wide range of models. A lot of them handle the simple attacks, like telling the model to ignore all its instructions. But they all have serious issues. They can all be hacked or prompt injected to some degree. There are sophisticated ways to sneak information in so the model does what the user wants and not what the provider of the model wants. None of them did a great job.
So no, I don't think AI models can be completely trusted. They're non-deterministic. They have randomness in them. They can't be fully trusted with anything important or secure.
Why Model Boundaries Will Never Be Completely Safe
Many of the solutions I see lean very hard on the model itself. They trust the model to take care of certain issues. They assume they can prompt their way out of certain problems. That's often why you see security issues, or models doing things they shouldn't.
I think there will almost always be attack vectors inside the model. Ways to trick it into giving up information or doing things it should not do. I don't see that being solved anytime soon. Maybe at some point. I highly doubt it.
When the model is the solution, with a little harness or window dressing around it, the solution can always be hijacked to some degree.
Build Hard Boundaries Around the Model
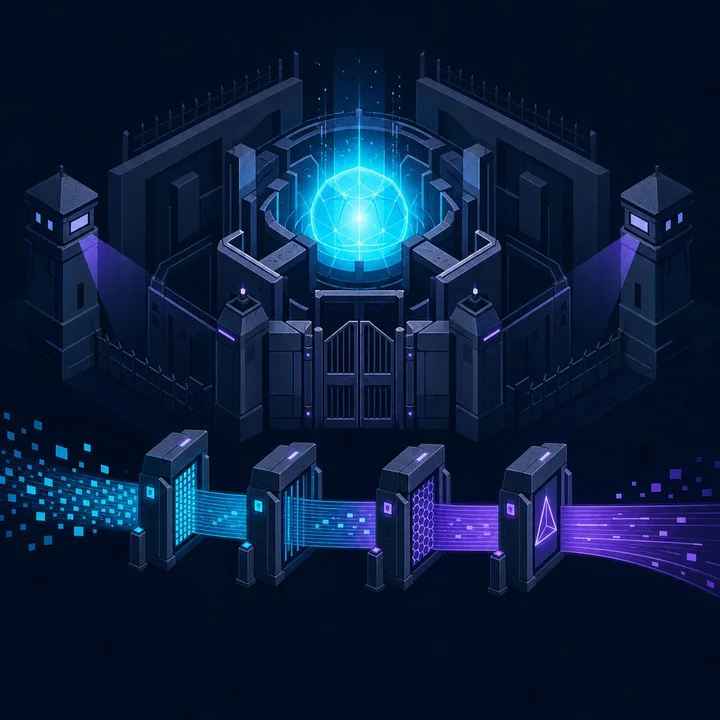
The fix is to flip the solution on its head. Instead of the model being the system, build a system with hard boundaries that don't depend on the model figuring out what's right or wrong.
- Demote the AI. Use it only at key steps you couldn't otherwise solve without AI.
- Narrow each ask. Ask the model to do less and less at each step, so you get much more reliable output.
- Add hard gates and filters. Put code-based, systems-level boundaries on top of the model. They shouldn't depend on the model finding problems, fixing problems, or deciding whether a prompt or input is safe.
The code controls the model, not the other way around. Do this and you get much more secure, much more reliable solutions.
I believe this is one of the main reasons so many companies building AI agents and AI solutions don't get reliable results.
They build AI model first. The better way is system first, with AI only at the places where classic code couldn't solve the problem. I make the same case in Don't Build AI Agents. Build AI-Powered Systems Instead.
What This Means for You
Hallucinations and security holes come from the same place. The model is generating random chunks of text, one at a time, and a certain percentage of the time it goes off track. Better prompts don't change that. A newer model built the same way doesn't fully change it either. So plan for it.
- If you use AI output, check it before you rely on it. Treat a confident answer the same as any other answer until it's verified.
- If you build with AI, put the controls in code, outside the model. Keep each AI step narrow. Measure the results with real AI evals, not vibes.
Trust but verify. That applies to every model, every time.
Frequently Asked Questions
Why does AI hallucinate?
LLMs generate text one chunk at a time with randomness. When the model picks a chunk that's a little off the rails, each following chunk builds on it and the error compounds, like losing control of a car on ice.
Have AI hallucinations been solved?
No. Thinking models can sometimes catch themselves and readjust, but not always. Fully fixing it would take a completely different architecture, so AI output will always need to be checked.
Can AI models be fully trusted?
No. In David Hood's red teaming research across a wide range of models, every model had serious issues and could be tricked or prompt injected to a significant degree.
Can you prompt a model into being secure?
Not reliably. There will almost always be attack vectors inside the model. Security needs hard, code-based boundaries that don't depend on the model deciding what's safe.
How do you build a more secure AI system?
Demote the AI to the key steps only it can do, ask it to do less at each step, and put hard gates and filters in code around it.
At 42 Robots AI we evaluate AI systems and build them system first. If you want to know where your AI needs hard boundaries, let's talk.